The Ontology & Portable Memory
Status: ✅ shipped (core ontology + domain extension + CLI). The Go ontology registry replaced the Python
pinard-corepackage. The broader multi-model store design is 🔭 designed — see The Layered Memory Architecture.
For a fleet’s knowledge to be queryable and portable, it has to be typed. Pinard types memory with a layered ontology and ships it as versioned, portable subsets.
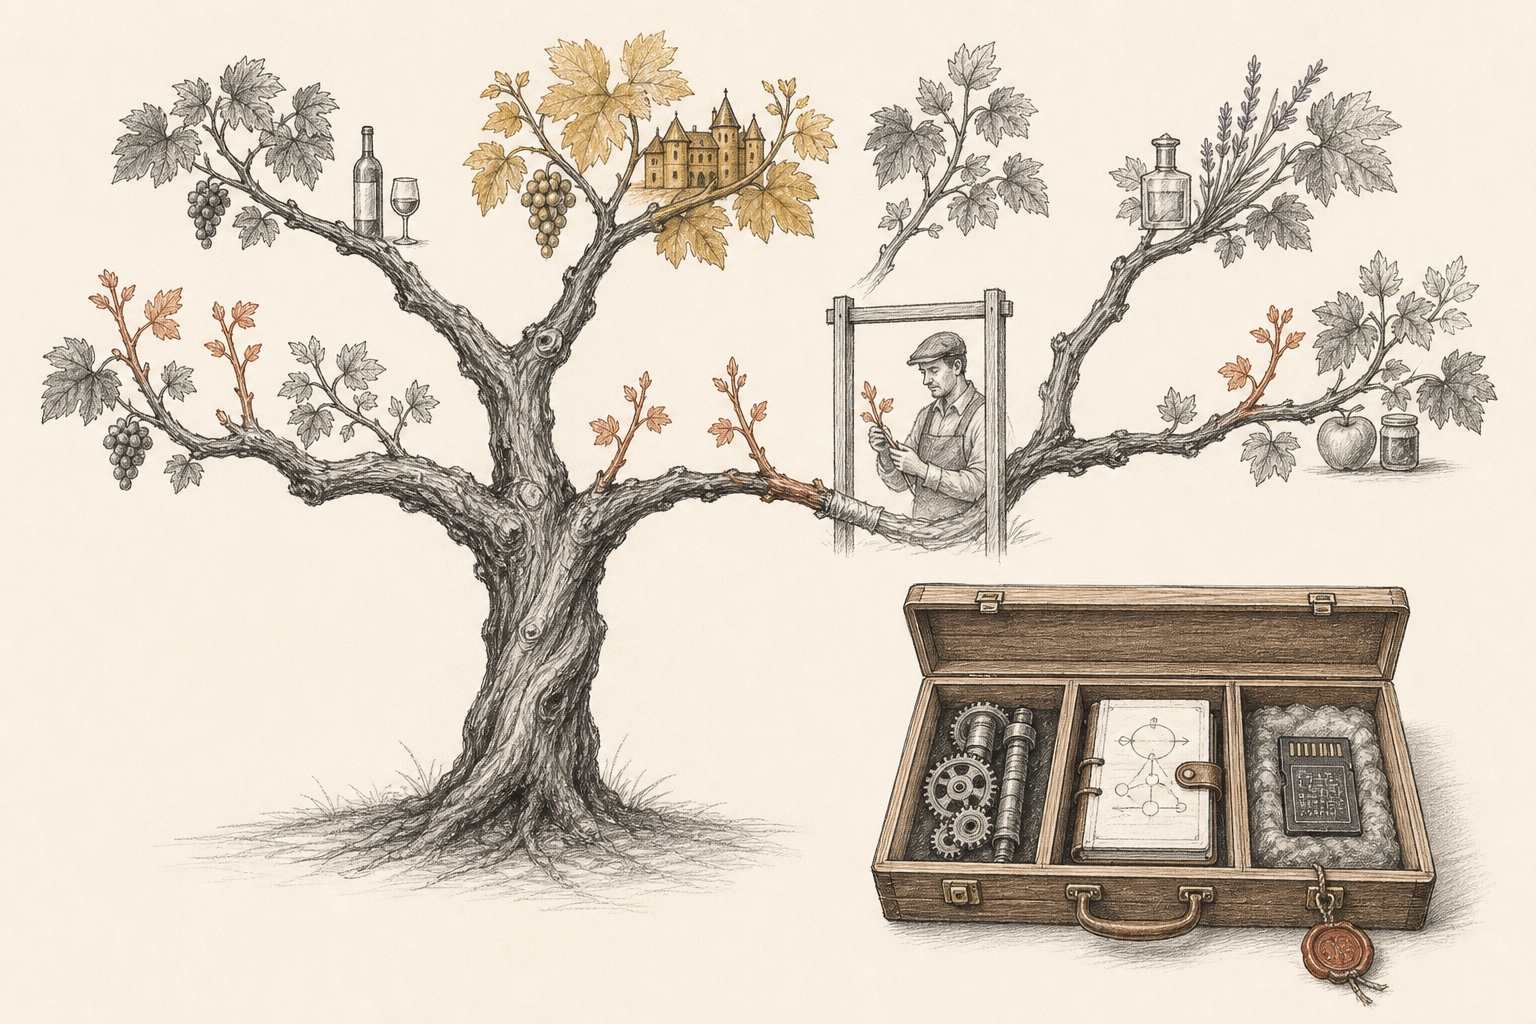 L1 ·
pinard-core
L2 · repository ontology
Learned types
Human-reviewed promotion
Portable agent · one versioned unit- L1
pinard-core— the small, stable operational trunk shared by every agent. - L2Repository ontology — domain concepts branch from and subclass the core.
- ↑Learned → promoted — only a reviewed, proven domain type is grafted toward core.
- ▣Portable agent — runtime,
process.js, and scoped memory are versioned together.
Why layered
A single flat ontology forces a false choice: either it is generic and useless, or it bakes one domain’s specifics (say, GWAS/HPC terms) into what should be shared by everyone. Pinard splits it into two layers instead.
Layer 1 — core ontology
Repo-agnostic, agent-operational concepts that mirror the primitives of a
semi-deterministic loop. Encoded as declarative
YAML embedded in the Pinard binary (internal/ontology/core.yaml) — no Python or
external runtime required. Small and stable, versioned centrally in Pinard:
- Entities:
task/step,verdict/decision,gate(a breakpoint),action,diagnosis,log_pattern,environment_condition,artifact. - Edges:
DependsOn,Produces,Consumes,IndicatesProblem,ResolvedBy,RequiresCondition,TriggersDecision.
Layer 2 — per-repo domain
Each repository defines its own ontology that subclasses core and lives next to
its process.js. For example, a GWAS pipeline repo might define:
SlurmJobis-aTask/executionShardThresholdDecisionis-aDecisionGWASStudyis-aArtifactProvenanceRecord
Granularity is per-repo by default (a per-process override only where a process
genuinely diverges; per-agent is too granular). A data-pipeline mid-layer between
core and domain is deferred but intended.
Writing a domain ontology file ✅
A domain ontology is a YAML file conforming to the Pinard meta-schema. Drop it in
your vigne’s pinard/ontology/ directory (see Domain extension loading
below) and the ingester picks it up automatically — no Pinard rebuild required.
domain: my-pipeline
version: "1.0.0"
group_ids:
  - my-pipeline-build

entities:
  pipeline_job:
    description: "A batch job submitted by the pipeline."
    is_a: task           # inherits task properties from core
    properties:
      job_id:
        type: integer
        description: "Job ID assigned at submission."
      partition:
        type: string
        description: "Compute partition the job ran on."

edges:
  SubmittedTo:
    pairs:
      - [pipeline_job, environment_condition]
File envelope fields:
| Field | Required | Notes |
|---|---|---|
domain | ✓ | Short identifier for your domain |
version | ✓ | Semver X.Y.Z |
entities | ✓ | Map of role-name → entity definition |
edges | ✓ | Map of edge-name → {pairs: [[src, tgt], …]} |
group_ids | — | Which group IDs this domain applies to (empty = applies to all) |
suppressed | — | List of core entity/edge names to remove from this composition |
Each entity entry:
description— requiredis_a— core role to inherit properties fromproperties— map of property-name → JSON Schema fragment (type,description,format,minimum,maximum,enum,items)required— list of required property names
Domain extension loading
The ingester discovers domain files at startup from:
PINARD_ONTOLOGY_DIRS— colon-separated list of directories scanned for*.yaml/*.yml/*.jsonfiles (for k8s / CI use).<vignoble>/pinard/ontology/*.{yaml,yml,json}— auto-discovered whenVIGNOBLE_DIRis set (the default in a local vignoble).
Missing directories are non-fatal (logged warning). Invalid files are skipped with a warning; valid siblings still load.
Composition semantics
Compose(group_id) = core + domain(group_id) − suppressed:
is_ainheritance — a domain entity withis_a: taskmerges task’s core properties under its own (domain properties win on key collision).- Edge extension — domain edges sharing a name with a core edge append their pairs rather than replacing the core pairs.
- Suppressed — role or edge names in
suppressedare excluded from the result.
CLI tools ✅
Two new aoc subcommands help domain authors validate and inspect their ontology:
# Validate a domain file — exit 0 on success, non-zero on error
aoc ontology validate path/to/my-pipeline.yaml
# ✓ my-pipeline.yaml is valid

# Inspect the composed result for a group_id
aoc ontology inspect --group-id my-pipeline-build
# Composed ontology for group_id="my-pipeline-build" (core 1.0.0 + domain my-pipeline@1.0.0):
# Entity roles:  task  step  verdict  decision  gate  action …  pipeline_job  …
# Edge types:    DependsOn (3 pairs)  …  SubmittedTo (1 pairs)
Use aoc ontology validate as a CI gate in domain repos to catch schema errors early.
Lifecycle: prescribed → learned → promoted
Types are not frozen. They move through a lifecycle:
- prescribed — declared up front (core, or a repo’s domain);
- learned — new types emerge during
/teachingsessions; - promoted — a proven domain type is elevated toward core.
Promotion domain → core is human-gated (a git PR), and a suppressed_types list
retires types that stop earning their place. This is the same recurrence-plus-review
pattern used for rule and scope promotion.
Portable memory subsets
This is the payoff of a single, embeddable store of record. The central memory (SurrealDB server) can be subset — scoped to a repo or pipeline — into a specialized embedded SurrealDB file that an agent loads locally.
That makes a pinard agent a self-contained, reproducible artifact:
 pinard agent  =  harness  +  babysitter process  +  memory subset
                  (the runtime) (the loop, process.js) (embedded, scoped store)
All three are versioned together (e.g. in ExoHub), so an agent-centric data pipeline is reproducible and auditable: you can rebuild exactly the agent, its loop, and the knowledge it had at a given version.
Version-stamping
Every portable subset version-stamps both the pinard-core ontology version and
the domain ontology version it was extracted under. A migration policy governs what
happens when core or domain versions change under an already-shipped subset — new,
load-bearing scope that portability introduces.
Next
- Teaching & Curation — how knowledge is captured, curated, and promoted.
- The Layered Memory Architecture — where the ontology sits in the stack.